

What we do · Storage and compute
GPU servers and private AI infrastructure
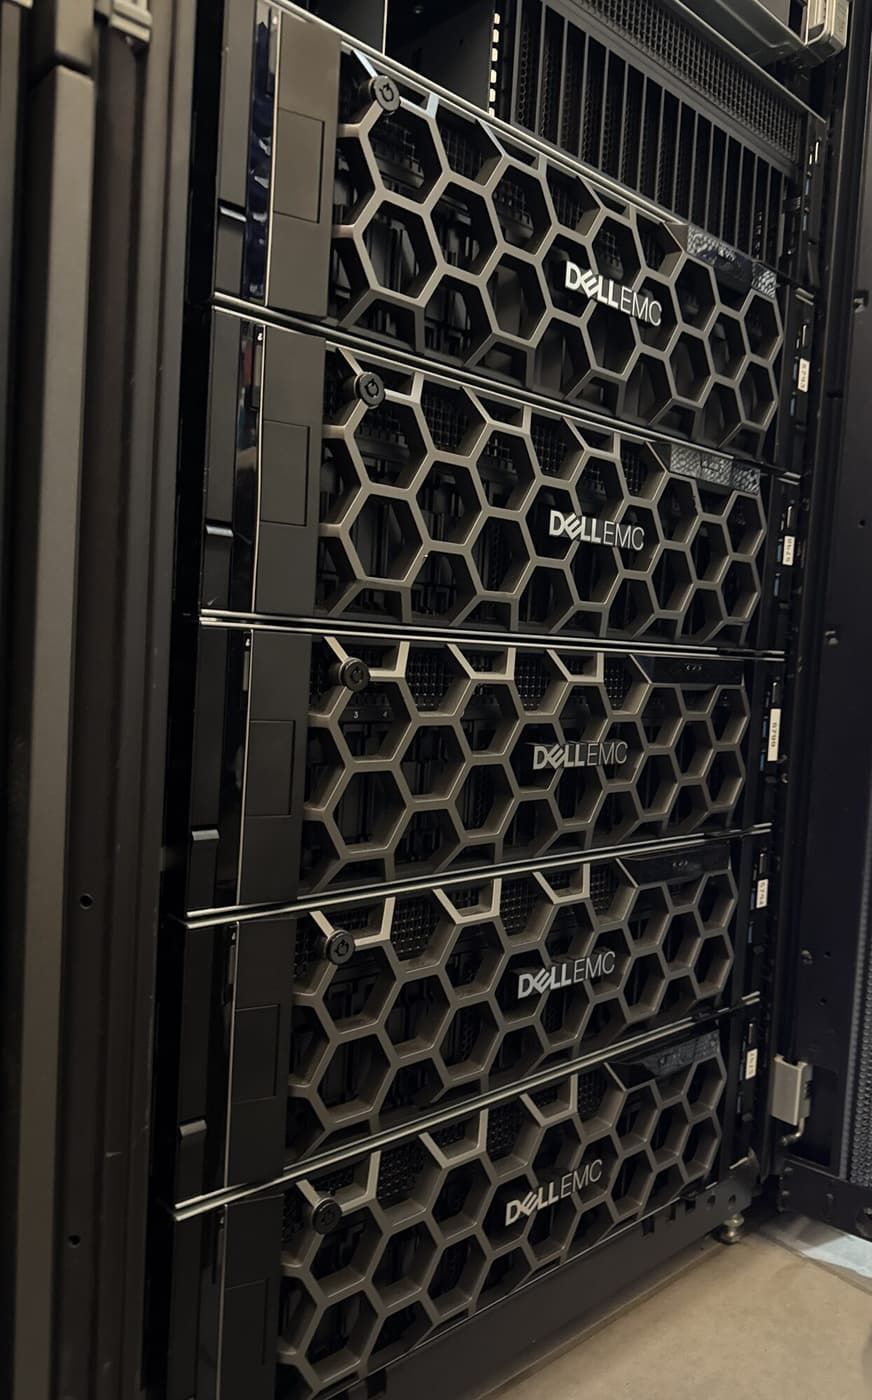
The GPU you need, in our datacenter, within 48 hours: NVIDIA L4, L40, L40S, A100, H100 and more. Run open-weight models for chat, search, extraction and analysis on hardware that is yours to use, so confidential data never goes near a public AI service.
What it is
Two things, sold separately or together. GPU servers: dedicated machines with the NVIDIA accelerators your workload calls for, on enterprise HPE and Dell platforms in our datacenters, delivered with a 48-hour lead time. Private AI: the full stack built on top of them, from model serving and embeddings to vector search and retrieval with citations, operated by our engineers, reachable only from your private network.
How we build it
Any current NVIDIA data center GPU. L4, L40, L40S, A100, H100 and the rest of the current range. We size the card to the model and the workload, not to a catalogue: a quantised large model on a single card for inference, several cards for training or high throughput, a smaller card for embeddings alongside.
Built the enterprise Linux way. Vendor-signed kernel modules, Podman with the NVIDIA container toolkit, SELinux enforcing.
Standard APIs, private endpoints. Models are served through OpenAI-compatible endpoints on an isolated network segment, so your applications change one base URL to move from a public API to your own models. Nothing in the content path calls an outside AI service.
Retrieval that cites its sources. For document and mail workloads we pair an embedding model with a vector database and a full-text index, so answers are grounded in your own documents and link back to them. Long document pipelines run extraction page by page, then cross-check the output against its own citations.
Storage that keeps up. Model weights, datasets and archives sit on our all-flash SAN or fast local NVMe, chosen by measurement.
What it protects you from
- Confidential data (medical, legal, financial, personnel) leaving the building or the jurisdiction.
- A per-token bill that grows with every successful month.
- An AI vendor changing terms, rate limits or prices on your best day.
- Waiting months for GPU capacity.
- An AI endpoint exposed on the public internet.
In practice
Medical records analysed without leaving Athens. We built a private AI platform for a customer who needed to analyse medical records: patient folders go in, a structured, cited report comes out, and every step runs on local models inside Digital Realty Athens. The data never touches a public cloud.
A commercial AI workload, replicated on private GPUs. For a coaching platform, we reproduced its AI pipeline end to end on our own hardware: seven analytical passes over a real session transcript, dozens of structured insights extracted in under a minute, with output closely matching the commercial service it was compared against, and no per-call cost.
Why EuroVPS
- Any current NVIDIA data center GPU, delivered in 48 hours.
- GPU servers and private AI in our Athens and Amsterdam datacenters, inside the EU.
- OpenAI-compatible endpoints, so moving off a public API is one line of code.
- Engineers who build the model stack, the storage and the network, not just rent you a card.
- Fixed costs, no per-token meter.
FAQ
Which GPUs can I get? Whatever your workload needs: L4, L40, L40S, A100, H100 and others. Tell us the model and the throughput you need and we will size it.
How long does it take? 48 hours.
Where are the GPU servers? In our Athens and Amsterdam datacenters.
Can you run the models for us, not just provide the hardware? Yes. We deploy, serve and operate open-weight models and the retrieval stack around them.
Will our data be used to train anything? No. Your data stays on your hardware in our datacenter. Nothing is sent to an outside model.
Can we keep using our existing code? Usually yes. Our endpoints speak the same API format most applications already use.
Your data, your models, our datacenter. Talk to an engineer about the GPU and the AI stack you need.
Your next infrastructure partner
Let’s look at
your setup.
Tell us what you run today and what needs to improve. An engineer will review your brief and help you plan the next step.
+357 222 32280
who will look after your infrastructure.
Let’s start with your setup.
A little context helps us start the right conversation.