
Private AI: Your own AI.
Your data stays in.
Your own modelsOpen-weight, served for you
Answers from your documentsRetrieval that cites its sources
A private endpointReachable only from your network
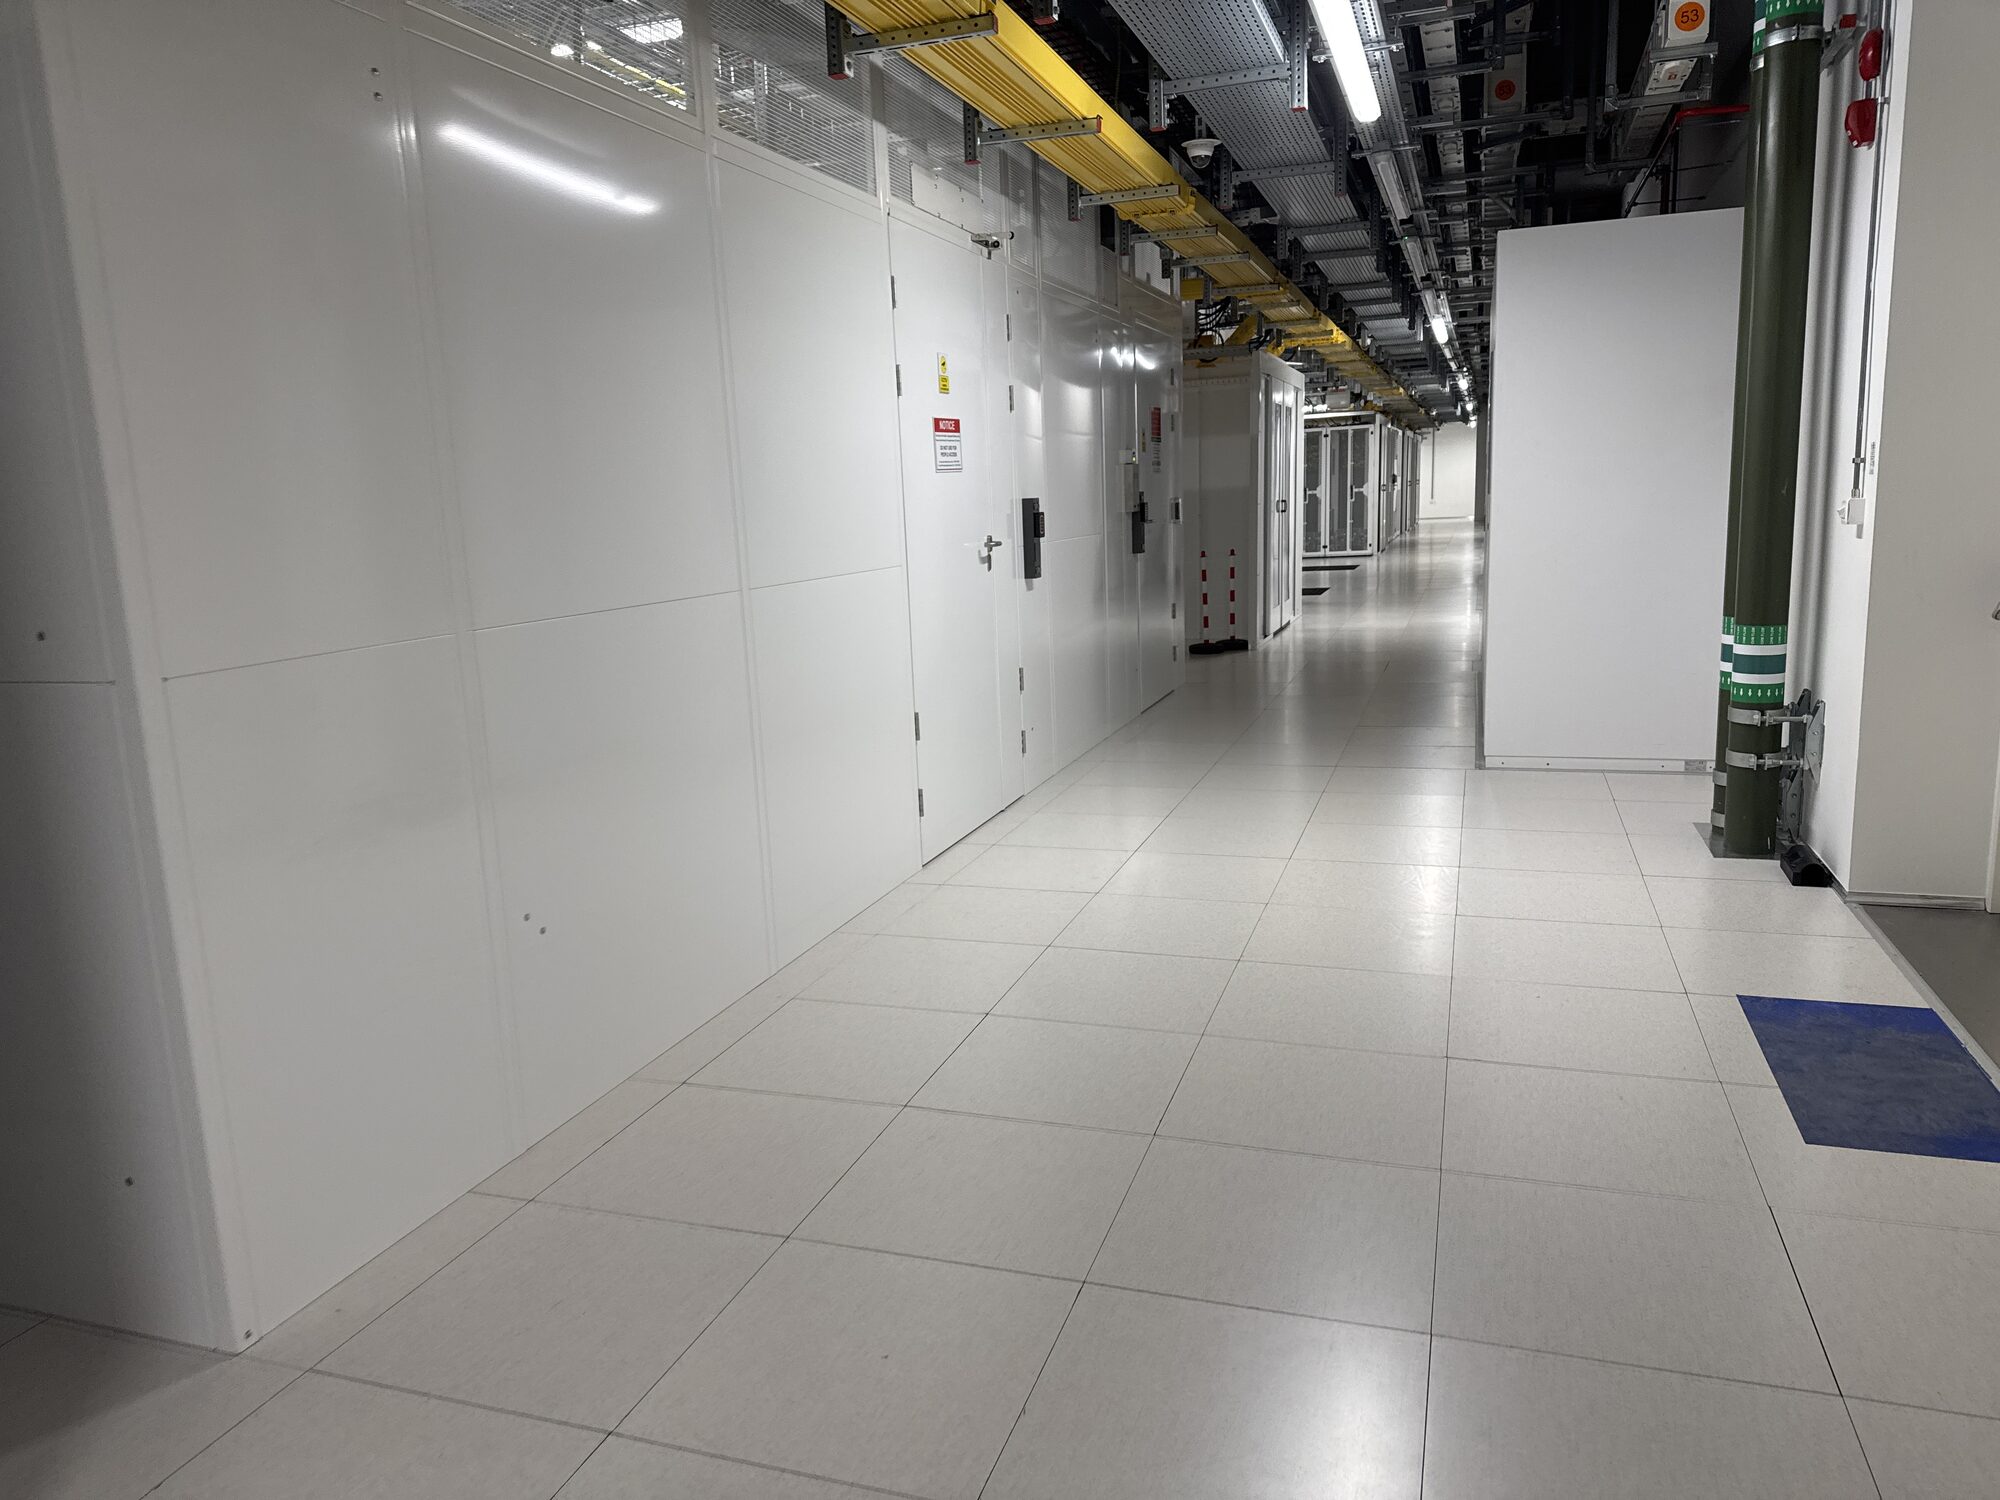
Inside the EUAthens and Amsterdam
Private AI or GPU servers
The outcome,
not just the card.
GPU servers are the hardware: dedicated machines with the NVIDIA accelerators your workload calls for. Private AI is the full stack built on top of them, from model serving and embeddings to vector search and retrieval with citations, operated by our engineers. Bring your own team to a GPU server, or let us run the whole stack for you.
See the GPU serversWho it is for
For data that cannot go
to a public AI service.
Medical, legal, financial and personnel records stay in the building and in the jurisdiction. The model comes to the data, not the other way round.
Talk to an engineerLegal
Contracts, case files and correspondence answered in plain language, without sending a document to a third-party API.
Health
Records analysed by local models, with every step of the pipeline running inside our datacenter.
Finance
Reports and filings searched and summarised on hardware under one jurisdiction, with the logs on your own machine.
Public sector
Workloads that must stay under EU law, placed in Digital Realty Athens or Amsterdam with one operator responsible for them.
Internal knowledge
An assistant that answers from your own contracts, tickets and wikis, and shows the passages it used.
Your own product
AI features in your application, served from a private endpoint your code calls like any other API.
What we run
The whole pipeline,
in one place.
The model is the small part. The documents, the embeddings made from them, every question and every answer are the sensitive surface, so all of it runs on your dedicated hardware.
Inside the GPU serversModel serving
Open-weight models such as Llama, Mistral, Qwen and DeepSeek, served through OpenAI-compatible endpoints, so your applications change one base URL to move from a public API to your own models.
Embeddings and retrieval
Your documents split into passages and encoded as embeddings in a vector database, paired with a full-text index, so answers are grounded in your documents and link back to them.
The API your apps call
A private endpoint on an isolated network segment, reachable only from your private network, with access, logging and retention agreed with you.
Storage and logs
Model weights, documents and indexes on our all-flash SAN or fast local NVMe, chosen by measurement. Prompts, outputs and access logs live on your machine.
The hardware underneath
Dedicated GPU servers with the NVIDIA accelerators the model needs, on enterprise HPE and Dell platforms in our datacenters.
How a deployment goes
From your workload
to a running endpoint.
Workload
We review the users, the documents, the models you have in mind and the requirements your data comes with.
Test
We test the proposed setup with your own prompts and documents before agreeing the hardware and the serving stack.
Build
Our engineers set up the hardware, the model serving, the retrieval pipeline and the private endpoint.
Run
The team that builds it stays responsible for operating it, with model updates planned and validated with your team.
In practice
Medical records analysed
without leaving Athens.
We built a private AI platform for a customer who needed to analyse medical records: patient folders go in, a structured, cited report comes out, and every step runs on local models inside Digital Realty Athens. The data never touches a public cloud.
Sized from your workload
Users, documents,
the models you want.
Answer a few questions about the people who will use it, the documents it should answer from and the models you have in mind. You get an architectural starting point, and an engineer reviews it with you.
Size your private AIBefore you start
Your data,
your questions.
Models, data handling, logs and cost. We work through them with your team, around what you need to run.
Ask an engineerGPU servers are the dedicated hardware. Private AI is the stack we build and operate on it: model serving, embeddings, retrieval over your documents and the private API your applications call. You can take the hardware on its own, or both.
Your next infrastructure partner
Bring us the documents
you want answered.
Tell us about your users, your documents and the models you have in mind. We will work through the stack, the hardware and the deployment with you.
+357 222 32280
who will look after your infrastructure.
Let’s start with your setup.
A little context helps us start the right conversation.
From the engineering team
The thinking behind private AI.
AI Hosting · 8 min read
A 70B model really does fit on a 48GB card, once you count what quantization costs.
Read the articleAI Hosting · 6 min read
Your AI endpoint doesn't have to be on the internet.
Read the articleAI Hosting · 5 min read