

Managed GPU infrastructure
Your model.
Your machine.
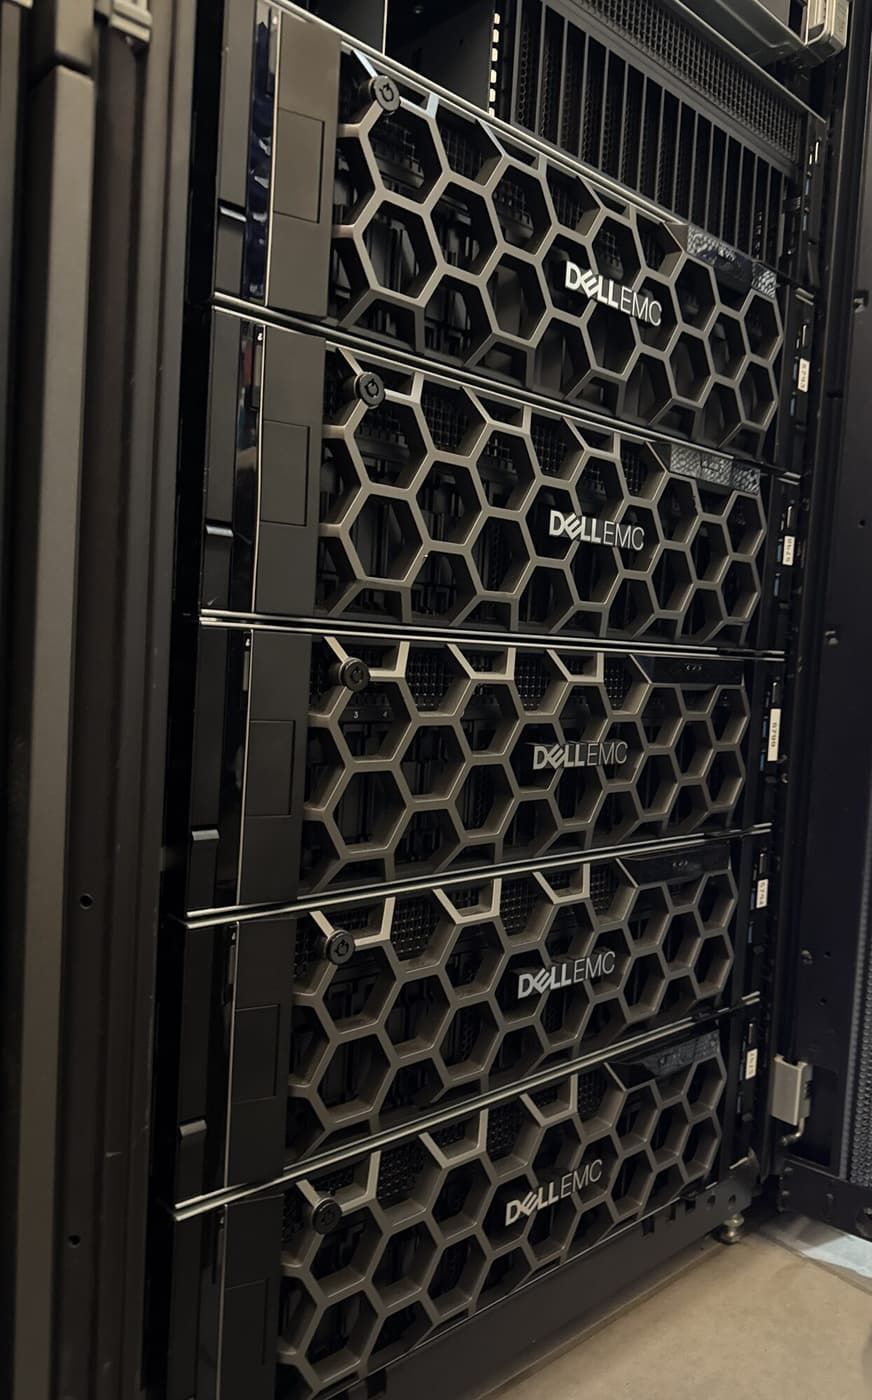
Dedicated GPUsCapacity reserved for you
A private endpointAccess designed around your app
Athens and AmsterdamDigital Realty, inside the EU
Managed by engineersFrom deployment to operations
The hardware
Any GPU we can buy.
In our datacenter within 48 hours.
NVIDIA L4, L40, L40S, A100, H100 and the rest of the current range, sized to the model and the workload. Your own private GPUs, in our Digital Realty datacenters in Athens and Amsterdam, inside the EU.
Model and machine, considered together
A model. A machine.
A plan.
Explore a few starting points for a private endpoint. We agree the exact model, serving requirements and hardware around what you need to run.
A private connection to the model on dedicated infrastructure.
Illustrative architectureA starting point for the conversation
Llama
- The model
- A 70B-class text model, current release agreed with you. We assess it against the language, quality and response-time needs of your application.
- The sizing
- We test precision, context length and concurrent requests together before choosing the GPU capacity and serving setup.
- Version and terms
- Llama ships under Meta's community license, which has its own use and scale conditions; we confirm the exact release fits your use before deployment.
A starting point for the conversation
Mistral
- The model
- A mid-sized model, current release agreed with you, is one option to evaluate for a private assistant or application endpoint.
- The sizing
- We agree the precision and context you need, then test the serving workload. Model size alone is not a guarantee of GPU fit.
- Version and terms
- Mistral publishes some weights under Apache 2.0 and some under its own research or commercial terms; we confirm which applies to the release you pick.
A starting point for the conversation
Qwen
- The model
- A family of model sizes. We choose a specific release to test against your application rather than size hardware for the family name.
- The sizing
- Start with the selected model and your own prompts. Context, precision and traffic targets guide the final configuration.
- Version and terms
- Review the terms for the exact model and size. The linked 72B model card is one example, not a license for the whole family.
Designed with you
DeepSeek
- The model
- A large mixture-of-experts model, current release agreed with you. It calls for a considered serving architecture and a workload assessment.
- The sizing
- Designed with you. We assess GPU memory, interconnects and deployment options before agreeing a build or a price.
- Version and terms
- The model terms are separate from the repository’s code license. Review the chosen release before deployment.
A starting point for the conversation
Not sure yet
- The model
- Start with what the application needs to do. We help you shortlist models to test on your own prompts and documents.
- The sizing
- We work through answer quality, response time and expected traffic with you, then agree the model and hardware together.
- Version and terms
- The shortlist includes the exact model versions and their terms, so the deployment decision is made with the details in view.
Final configuration and pricing agreed after sizing.
The engineering is part of it
We do the engineering.
You call an endpoint.
One team for the hardware, serving stack and day-to-day operation. You bring the workload; we work through the details with you.
Meet your support teamA model and a machine that fit
We work through the model, memory and expected concurrency, then test the proposed setup with your prompts.
The serving stack, set up
GPU drivers, the inference runtime and endpoint configuration. Our engineers handle the infrastructure around your model.
Access on your terms
A private endpoint with network access and logging configured around your applications and data requirements.
Managed beyond deployment
The team that sets up the machine stays responsible for operations, investigating issues across the host and serving stack.
Updates, with a plan
Keep a chosen model version, then validate changes and agree the update window before moving to the next one.
Capacity that follows demand
We review memory, context length and concurrency with you as usage grows, and add GPUs or a second host when the numbers say so.
What will you run?
Four illustrative workloads. We shape the model, private access and capacity around your application.
RAG over private documents
Bring retrieval and inference onto managed infrastructure. Build answers from approved documents, with citations back to the source.
- Model, embeddings and vector database together
- Document access over VPN or a private network
An internal assistant
Give your team an assistant over approved internal knowledge, with access and prompt logging configured around your organisation.
- Dedicated inference for your team
- Logging and retention agreed with you
AI features in your product
Serve model responses through an endpoint your application calls. Agree the model version and size capacity against real prompts and expected demand.
- Inference on your managed GPU infrastructure
- Capacity and concurrency tested for your application
Code assistance on private source
Run a code model with approved repository context and private access. Keep inference and source data on managed infrastructure, with completions returned to your team.
- Selected files and retrieved code as context
- Repository access scoped to authorised users
A private AI build
Medical records analysed
without leaving Athens.
A customer needed AI to analyse medical records: patient folders go in, a structured, cited report comes out, and every step runs on local models on the customer's own private GPUs inside Digital Realty Athens. The data never touches a public cloud.
Before you deploy
The model is
only the start.
Memory, access, cost and ongoing operation. Let’s work through what your endpoint needs.
Ask an engineerWe work with open-weight models including Llama, Mistral, Qwen and DeepSeek. The exact release, serving software, hardware needs and license terms are reviewed for your deployment. If you have not chosen a model, we can shortlist options and test them on your prompts.
Your next infrastructure partner
Bring us the model
you want to run.
Tell us about your model, data and expected workload. We’ll work through the hardware, serving stack and deployment with you.
+357 222 32280
who will look after your infrastructure.
Let’s start with your setup.
A little context helps us start the right conversation.
From the engineering team