
What is Hypertext Transfer Protocol (HTTP) anyway?
HTTP from the first request line to HTTP/2: methods, headers, status codes, keep-alive and what each means for a server you run.
The creation of the World Wide Web was refined through the years of about 1988 to 1991.
Originally, HTTP mechanisms were designed for allowing scientists from around the globe to share a research and collaboration platform. As it turns out, the world wide web has put publishing, learning and collaboration tools in the grasp of anyone with an Internet connection.
The original components behind Tim Berners-Lee's invention are still in use today. As a matter of fact, some modern day web-servers still understand the original HTTP specification (even though considered obsoleted today):
Basic Components of the World-Wide-Web:
- a web server
- a user agent
- textual display
- Media Types
- a protocol allowing transfer of documents, HTTP
| Modern Day W.W.W. | |
| web server | IIS, Apache, NGiNX |
| user agent | CuRL, Chrome, Firefox, RSS Readers |
| textual data | UTF-8, ASCII, JSON, HTML, XML, CSS |
| media types | textual data, images, video, animations |
| HTTP specs | HTTP/1.1 (RFC 9112), HTTP/2 (RFC 9113) and HTTP/3 (RFC 9114), with shared semantics in RFC 9110 |
Two primary entities are tasked with defining modern HTTP progression:
-
W3C World Wide Web Consortium The W3C is concerned with the functionality of web-servers, future specification needs, user agents (or web browsers), HTML, XML, video, images and content delivery technologies. More or less, the W3C is concerned with effects of HTTP on the Application Layer.
-
IETF Internet Engineering TaskForce IETF is concerned with how HTTP will work and function on a lower technical level. HTTP works on the top of underlying technologies such as IPv4, TCP, UDP, Ethernet and much more lower layer protocols. All lower protocols work together in getting data from user-agent to web-server, back to the user agent.
How are Standards Like HTTP Defined?
When an Internet protocol like HTTP is adopted or revised standards are defined in documents called an RFC.
RFC stands for Request For Comments.
Every recognized data-communications protocol accepted for mainstream Internet usage will be defined in a series of RFC documents. Technologies like HTTP, IPv4, TLS, PKI, SNMP, POP3 and even Ethernet are not technologies owned by Microsoft, Apple, or Google.
Standards defined in an RFC are meant to be adopted as means of allowing communications across multiple vendor platforms. Each technology (at its core) documented in a RFC can be implemented, refined for use, and even added to products by any person or vendor free of royalties or patents.
An RFC is usually a rather dry document available in ASCII text, keeping with the tradition of being readable across any platform. An RFC will also assume the reader proficient in technical concepts.
- The current HTTP specifications: RFC 9110 HTTP Semantics, RFC 9112 HTTP/1.1, RFC 9113 HTTP/2 and RFC 9114 HTTP/3
HTTP is an acronym for Hyper Text Transfer Protocol. HTTP is a stateless, application layer protocol designed for communicating exchanges of information between systems across the Internet. As such, HTTP defines a set of rules allowing both transfer and access to remote documents. HTTP also has been used for transferring information in other ways such as SSDP which uses UDP and multicast addressing (adopted as HTTPU) for information transfers.
What HTTP is NOT?
HTTP and the world-wide-web are not the Internet. HTTP is a protocol powering an extremely popular portion of the Internet known as the world wide web.
HTTP operates above underlying network communication protocols in the TCP/IP model. TCP/IP is a mechanism for transferring data, framing information, and application layer data over the Internet. HTTP is an application level standard specializing at transferring a certain type of data. HTTP/1.1 and HTTP/2 run over TCP, while HTTP/3 runs over QUIC, which is built on UDP.
TCP/IP is a data-communication protocol suite developed by the Department of Defense from the USA. TCP/IP may sometimes be referred to as "the DoD networking model".
In its early years the Internet and TCP/IP were donated from DARPA labs to academia. After being refined for academic use the Internet was adopted by consumers and corporations to become what we know as the Internet of today. It was during the period of transition from academia to early public use HTTP and the world-wide-web were introduced.
| TCP/IP | Layer Protocols |
|---|---|
| Application Layer |
|
| Transport Layer |
|
| Internet Layer |
|
| Link Layer |
|
The above table is a representation of how HTTP fits into the Internet and TCP/IP.
Specifications For HTTP
Primarily, HTTP is for communicating transfers of documents between a user agent and web server.
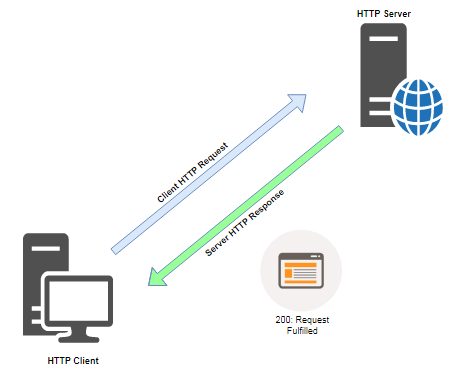
HTTP exchanges usually consist of the user agent requesting a series of documents from a web server. When an HTTP request is received by the web server it will analyze the request. Finally, the web server either returns a document and status code or may deny a request by returning a status code as to why a request was denied.
- For details specific to why a web server may deny a client request please refer to HTTP 400 Status Code section
User-Agent is a fancy term given to an application requesting HTTP resources from a web server. Most commonly user agents are known as a web-browser. However, RSS Readers, Web Scraping Bots, web spiders, and HTTP libraries like CURL are user-agents as well.
Web Server is a daemon commonly running on port 80 (HTTP) and port 443 (HTTPS), specifically purposed for retrieving documents from a designated portion of the server's filesystem for delivery to a user agent.
The three most common high-load web-servers on the Internet today are Apache, Nginx (pronounced Engine-X), and IIS (from Microsoft).
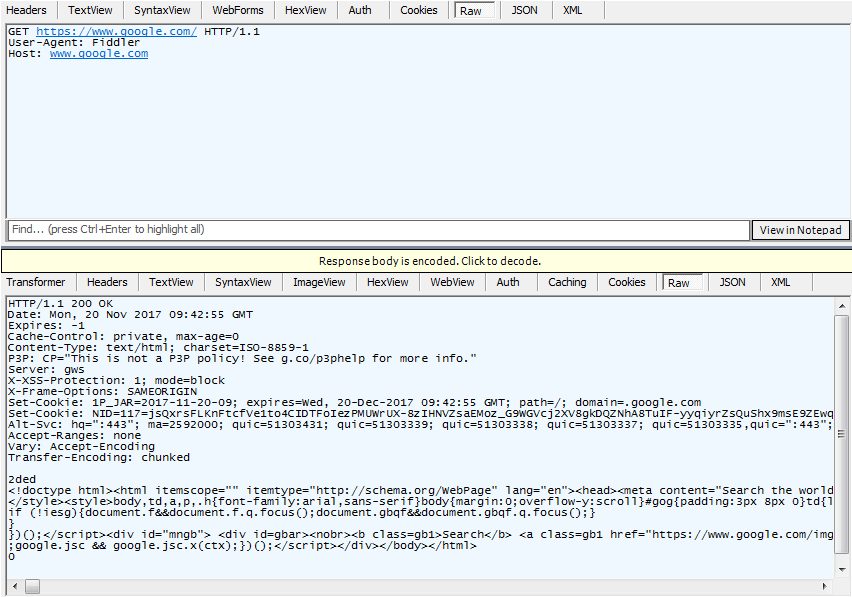
Let's look at a simple HTTP request with a user-agent application named Fiddler.
Fiddler is an HTTP debugging proxy for APIs and web applications; the developer tools built into every modern browser show much of the same information.
HTTP Request Methods
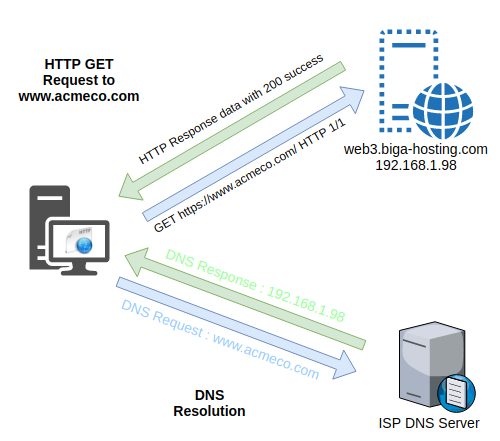
Just as displayed in the first diagram of an HTTP request/response exchange, the user-agent requests a document then a web server fulfills a valid HTTP request.
Shown in the top portion of the Fiddler UI window, Fiddler, the user-agent sent three lines of data:
- GET specifies file and path
- User-Agent identifies client software
- HOST specifies host where content is located
The Request Method is GET in this request. We will learn of other HTTP Request Methods in this primer.
The User-Agent String: A User-Agent string is how the web-client software identifies itself to the web server. API's and websites will often grant or deny access privileges and display-settings based on the client's User-Agent string.
Well-behaved crawlers identify themselves honestly in their User-Agent string and follow the rules a site publishes in its robots.txt file.
| Some example User-Agent strings (version numbers change with every release): | |
| Chrome on Windows 7 |
|
| Internet Explorer 11 |
|
| Googlebot |
|
| Play Station 4 |
|
Host
The Host header specifies the server (and domain) which possesses the requested document. Since HTTP/1.1 the Host header is required (HTTP/2 and HTTP/3 carry the same information in the :authority field). It is required because many websites share one server and one IP address, a setup called name-based virtual hosting, and the server needs the Host header to know which site a request is for.
A host IP address of 192.168.1.98 may have an external DNS name of web3.biga-hosting.com. This server named web3.biga-hosting.com can host hundreds of domains. In turn, the HTTP host header will let the server know to which hosted domain a request is destined. Multiple virtual domains can have the same IPv4 address of 192.168.1.98 (reverse DNS will usually point to web3.biga-hosting.com).
Dissecting HTTP
This section will delve a little deeper into interworkings of the HTTP Protocol. Topics discussed giving an overview of HTTP include:
- URI and URL concepts
- HTTP Verbs:
- GET
- POST
- PUT
- DELETE
- HEAD
- TRACE
- OPTIONS
- Media Types
- Common HTTP Characteristics:
- stateless
- no encryption built in
- HTTP Authentication
URI and URL Concepts
Of all concepts encompassing HTTP deciphering the terms URI and URL are simple yet still confusing amongst both students and even some developers. To further confuse a simple concept the term URI has been refined and documented in standards allowing the term URL to be synonymous with URI.
URI is an acronym for Uniform Resource Identifier. URL is an acronym for Uniform Resource Locator.
Let's define each in the simplest terms possible, using an analogy. In our scenario let's say URI is analogous to the term automobile. A URL is a specific type of URI. So let's say URL is analogous to a "car" but not a truck or a van.
However, it is advised to always use the term URI if a difference matters in any significance.
To further understand the concept of a URI let's now say we want to locate a book. But don't know where the book is located? We could not use a URL since a URL is host specific. We could, however, use a URN:
urn:isbn:0451450523
When using a URN as depicted, an underlying web application is tasked with the business-logic of locating a requested document.
Let's say in our analogy a URN is a van, another specific type of automobile. A URI defines a URN and URL. A URN identifies a specific resource, in our example a book. While a URL identifies location and other means for accessing a resource.
Dissecting a URL
A URL, otherwise known as a Uniform Resource Locator is the most common URI in use on the world wide web. This is what we enter into the address bar of a web browser to get https://www.google.com.
Let's take a look at more complex URL and break each part down:
http://admin:password@web5.acmeco.com:8080/admin-docs/2017/ins/infrastructure.xlsx
It is syntactically valid, but it shows something you should never do.
The user:password form in a URL is deprecated (RFC 3986), and modern browsers strip or block it. Credentials in a URL end up in server logs, browser history and Referer headers. Never put credentials, hashed or not, in a URL.
| URL Credentials | |
| scheme | http:// |
| credentials | admin:password |
| resource/host | web5.acmeco.com |
| port | 8080 |
| path | /admin-docs/2017/ins/ |
| document | infrastructure.xlsx |
http://www.acmeco.com/ is also a valid URL.
The appended forward slash tells the web-server we want the default document in the webroot. Traditionally this document is named index.html but can be modified to anything by server's Administrator.
Another valid URL can be: mailto:user@example.com. Instead of requesting a document, this URL opens the default mail client, ready to write to that address.
Some valid URL protocol schemes are: https://, http://, ftp://, file://, mailto:, tel:, and probably a few more. http and https are the most commonly used protocols on the world wide web, however.
Query Strings
Another common way for specifying a URL exists and is commonly used on the world-wide-web. It is called a query string. A query string is usually used in conjunction with a back-end web-application or a CGI script.
An example is appended to our previous GET request directly accessing Google Search:
https://www.google.com/search?q=euro+vps
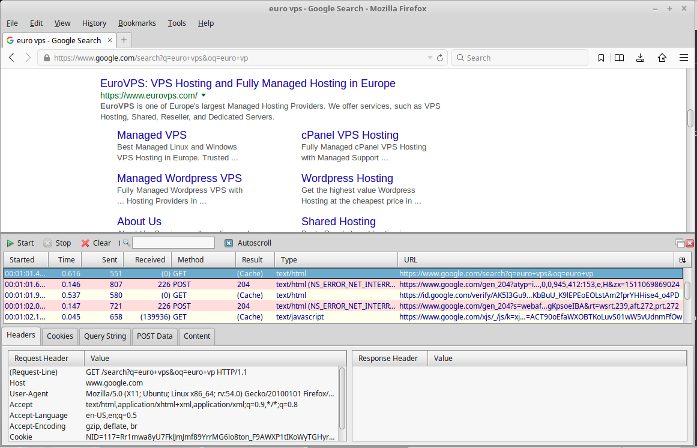
Query strings are usually used for passing parameters to a backend script. The Query string is encoded by the web-browser, then delivered to a web-server, decoded by the web server or application, then finally processed by the web-application.
Query strings have been known to be exploited by passing bad parameters in attempts to manipulate functionality of a web application.
https://www.acmeco.com/auth/auth.php?user=acmeuser&password=EXAMPLE
Above is an example of what never to do. Credentials, hashed or not, must never travel in a URL: they end up in HTTP logs, browser history and Referer headers. Send them in the body of a POST over HTTPS, or in an Authorization header.
HTTP Verbs
Now that we have a good idea of what a URL is and how query strings are used, we will introduce verbs used for HTTP Requests. The most commonly used HTTP verbs are:
- POST & GET
- PUT
- DELETE
- HEAD
- TRACE
- OPTIONS
- CONNECT
1. POST and GET
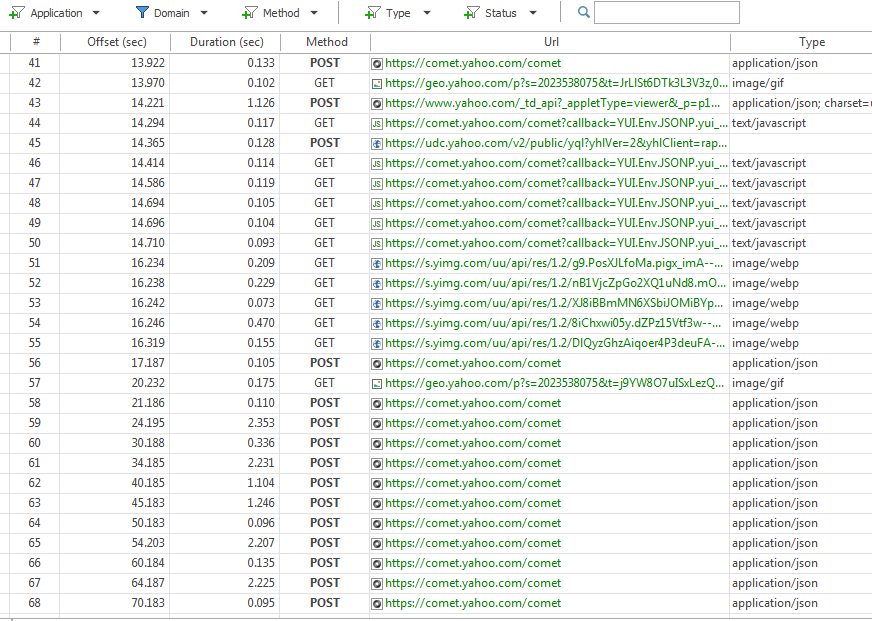
GET is the default method used when typing a website into a web-browser's address bar or clicking a hyperlink. When a webpage is requested, the web-browser can actually make several GET or POST requests downloading all resources composing a webpage including images, stylesheets, client-side scripts, typography resources, and more:
hyperlink is the technical name for linking to secondary webpages. When the user clicks on a link (or hyperlink), the webbrowser sends a GET request for the linked page
POST Requests
The two most commonly used request methods are GET and POST. We have already broken down a GET request. So let's examine a POST request.
What if we wanted to upload a 1GB file via a PHP or asp script? Naturally, a URL cannot hold a 1GB binary string. We would use the POST method in this scenario.
POST is similar to GET in that POST can pass parameters like a query string. However, POST data is not appended to a URL like with the query string.
Instead, POST data travels in the body of the HTTP request, after the headers. POST is most commonly used with HTML form data.
The POST method is commonly used when the following features are needed:
- file uploads
- keeping sensitive data out of the URL
- longer data strings need to be sent
- different encoding schemes must be used
- cannot be cached (if a security concern)
Let's compare with some advantages of the GET method with a query string appended to the URL
- can be saved as a bookmark
- can be cached
- query results can be shared with a link
2. PUT
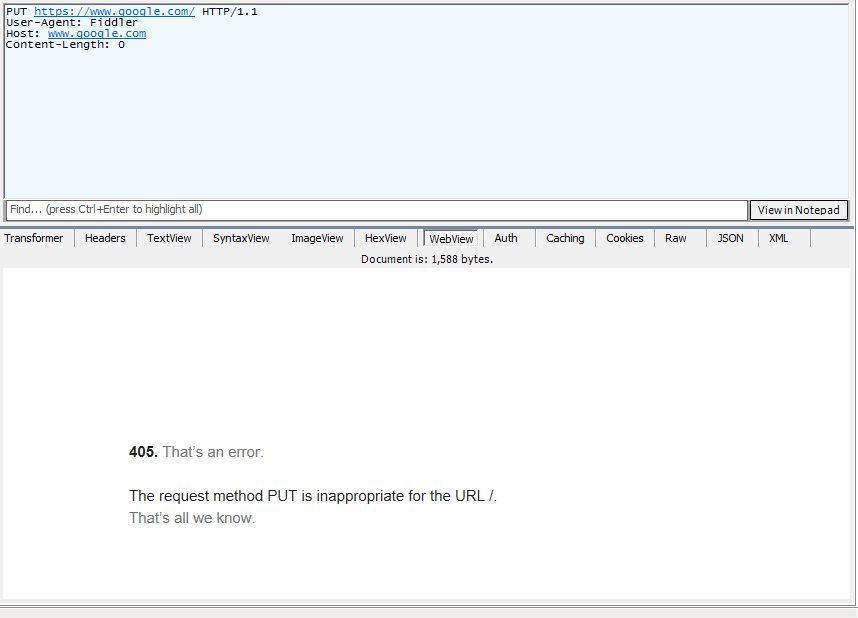
The PUT method is most often used in RESTful web API's. PUT creates or replaces the resource at the URI given in the request, while POST asks the server to process the data, often creating a new resource at a URI the server chooses.
PUT is usually disabled by default on web server installations.
Leaving PUT enabled could potentially allow attackers the ability to upload and execute files on the web server.
3. DELETE
Like PUT the DELETE method is most commonly used in RESTful API's. Using DELETE should perform a delete action on a URI object:
DELETE http://acmeco.com/customers/{customer-id}
DELETE is disabled by default on most web server installations. Enabling DELETE when unneeded could be a security risk allowing attackers to delete documents from a website.
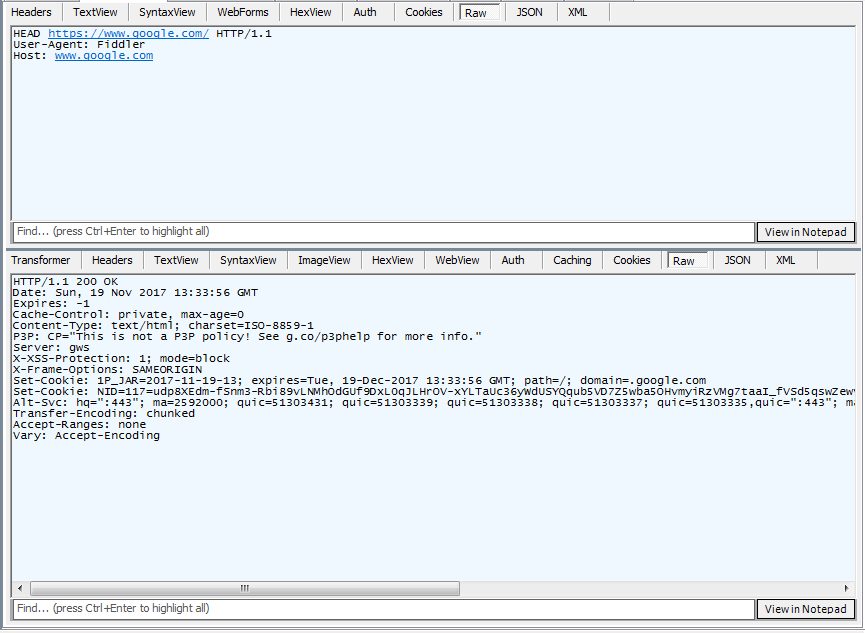
4. HEAD
The HEAD method is a similar method to GET but returns only headers with no content. HEAD is commonly used to check if a cached document has been updated. If the document is newer than a cached version the entire document will be downloaded and cached.
5. TRACE
TRACE is a diagnostics method and will usually be disabled on most web-servers. Many security researchers have discovered potential vulnerabilities with TRACE methods. Liability by far outweighs usefulness with TRACE most times.
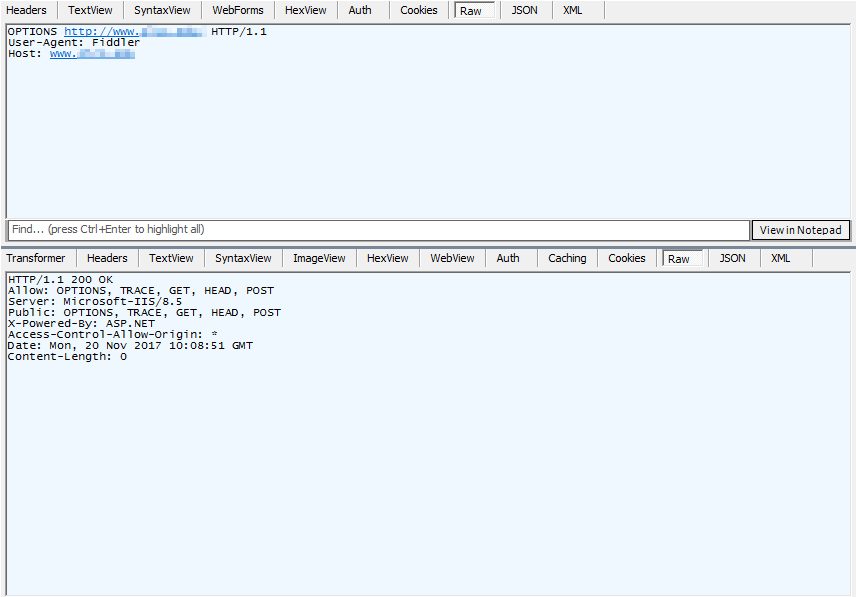
6. OPTIONS
OPTIONS asks the server which methods and features it supports for a resource. Do not disable it: browsers send an OPTIONS request as the CORS preflight before many cross-origin API calls, and blocking it breaks those applications. Instead, allow only the methods your application actually needs, and disable TRACE.
7. CONNECT
CONNECT is used by proxies and should not be enabled on an ordinary web server. When enabled and misconfigured, CONNECT can allow connections to proxy requests to other servers. These proxied connections can be used for attacks or downloading illegal files.
By default, most web server software will have CONNECT disabled.
Legitimate CONNECT usage is tunnelling HTTPS and other TLS connections through a forward proxy.
Media Types
A Media Type defines files based on nature and format for display or processing. The Content-Type header is used in an HTTP response allowing a web-browser to display response text, load a plugin for a supported filetype, or simply download a file for viewing in a different application.
Originally Media Type was implemented for email attachments and coined MIME Types. MIME stands for Multipurpose Internet Mail Extension.
Some Media-Types may be prefixed with a "x-" or a "vnd". The "x" means a Media Type is not officially listed by IANA (Internet Assigned Numbers Authority). The "vnd" portion means a Media-Type is vendor specific (for example application/vnd.ms-excel).
Viewing Media-Types in Firefox
- type "about:config" in the address bar.
- in the configuration search box type "mime"
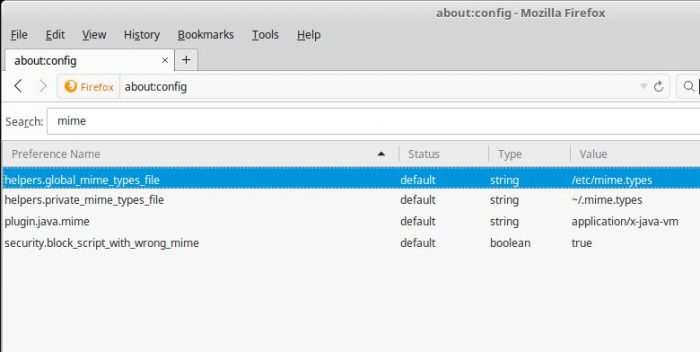
On a Linux platform we can see Firefox uses the file /etc/mime.types
Let's take a look at a portion of our /etc/mime.types file:
$ head -n 40 /etc/mime.types | grep -v "^#"
application/activemessage
application/andrew-inset			ez
application/annodex				anx
application/applefile
application/atom+xml				atom
application/atomcat+xml				atomcat
application/atomicmail
application/atomserv+xml			atomsrv
application/batch-SMTP
application/bbolin				lin
application/beep+xml
application/cals-1840
application/commonground
application/cu-seeme				cu
application/cybercash
$ wc -l /etc/mime.types
835 /etc/mime.types
As shown, over 800 specific mime-types are recognized by this system. In essence this tells Firefox about extensions associated with certain filetypes.
NOTE: Media-Types are different from the operating system "default applications". While similar in concept, mime types are used for internet-aware applications while an operating system keeps a separate record of filetypes and associated viewers.
When a GET request is made for an Excel spreadsheet, the Content-Type header returns application/vnd.ms-excel. In turn, the web-browser knows the file should not be displayed as text in the browser window. Instead, the file is either loaded into a plugin viewer or downloaded for later viewing in a different application.
A Unix or Linux web-server also uses /etc/mime.types for the Content-Type header. In addition, a handler must be set for a scripting language such as php, so that PHP files are executed rather than sent to the browser as text. On RHEL, Apache's /etc/httpd/conf.d/php.conf hands them to PHP-FPM:
<FilesMatch \.(php|phar)$>
    SetHandler "proxy:unix:/run/php-fpm/www.sock|fcgi://localhost"
</FilesMatch>
Above: files ending in .php (and .phar) are passed to the PHP-FPM service through its socket instead of being served as plain files.
If you have ever clicked a link only to have a graphic or other binary data displayed as ASCII by your web-browser or have been prompted to download a web-page, it means the browser or server mime-types were misconfigured.
To trouble-shoot, look at the Content-Type Header in your browser's developer tools (Network tab):
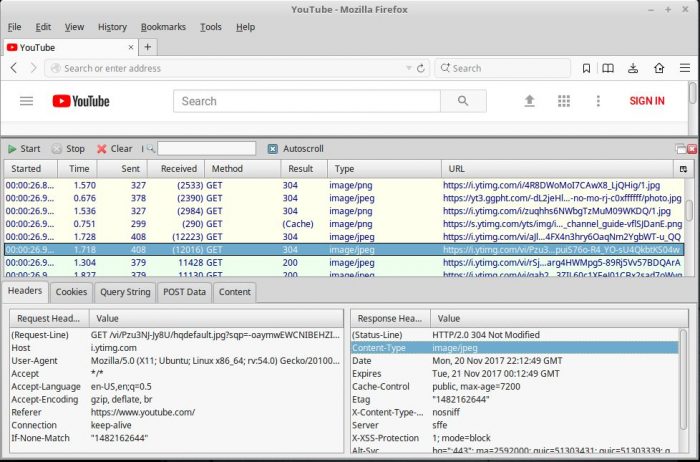
We can see the correct content-type was specified in a server response. If the browser were prompting to save the requested image from the get request, we'd know the browser mimetype for image/jpeg needs to be reconfigured.
Improper configurations of server-side-scripting or binary mime-types can lead to security issues on the server or client.
IANA (Internet Assigned Numbers Authority) is tasked with keeping an official mapping of media-types through RFC status.
HTTP Characteristics
In this section, we will discuss characteristics of the HTTP protocol. The most important concepts to know when working with HTTP are:
- HTTP is stateless
- HTTP does not offer built-in encryption
What is a Stateless Protocol?
HTTP is stateless by design: each request carries everything the server needs to answer it. HTTP is not connectionless, though. HTTP/1.1 and HTTP/2 keep TCP connections open and reuse them for many requests, and HTTP/3 does the same over QUIC.
Stateless simply means HTTP transactions are requested by a user-agent then responded to by the web-server. If a client doesn't cache requested resources it must then issue the same method to again obtain the resource. An HTTP web server has no state table to lookup previous communications with a user-agent.
HTTP Cookies: cookies can assist a web-server in referencing past HTTP interactions with a user-agent. The protocol itself remains stateless: each request stands on its own, even when it travels over a connection that is reused.
Most back-end programming languages such as Python's Django Framework, PHP, and ASP .Net offer libraries for maintaining application state with built-in session frameworks. This approach does add statefulness to a web-application, but is abstracted at a higher level than HTTP.
HTTP Does Not Provide Encryption
HTTP itself does not provide built-in encryption mechanisms. Encryption is left to other protocols defining HTTPS. HTTPS uses Transport Layer Security or TLS, the successor to SSL.
TLS works with many protocols, not just HTTP. HTTPS is designed for carrying HTTP content-data and HTTP headers over secured TLS connections. SSL was originally developed in the 1990's by Netscape. The IETF later standardised its successor as TLS. All versions of SSL are now obsolete; TLS 1.2 and TLS 1.3 are current.
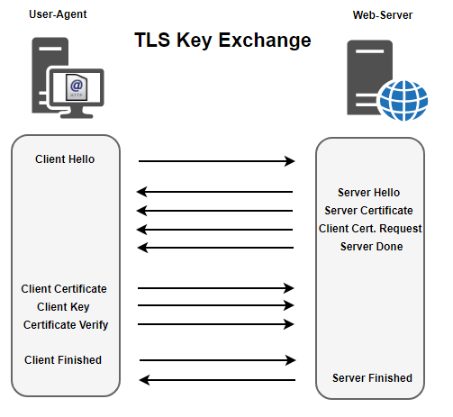
The astute reader may wonder, "So HTTPS is stateful? Right? Each session does have a key? Right?". Keys are cached by the client, yes. But TLS is still functioning at a lower layer than the HTTP core of HTTPS. Interactions with the web-server are still using the same HTTP Methods: GET, POST, PUT, and DELETE.
HTTP Authentication
Authentication, unlike encryption, is built into HTTP. HTTP supports multiple types of authentication types including:
- Basic
- Bearer
- Digest
- HOBA
- Mutual
- Negotiate
- OAuth
- SCRAM-SHA1
- SCRAM-SHA256
- vapid
Basic Authentication
By far the most common method of HTTP authentication is Basic Authentication. Basic Authentication is common because it is simple to implement, not because it is secure. Other authentication schemes are more secure, and Basic Authentication must only ever be used over HTTPS.
The greatest security issue with Basic Authentication is that credentials are being sent in clear-text. While credentials are encoded using Base-64, encoding is not encryption but is obfuscated at best. Credentials can easily be compromised when not using TLS or when TLS web-traffic falls victim to a man-in-the-middle attack.
Basic Authentication Shortcomings:
- encodes credentials in BASE 64 only
- credentials are cached in browser leaving another attack vector
- credentials can be permanently stored in the browser
- rogue proxy servers can potentially log credentials
- credentials are in the HTTP header
BASIC Authentication still does still serve a purpose. However, limitations of that purpose are important to acknowledge. Basic Authentication is good for access control only. Access Control is simply meant for controlling access to resources. Basic Authentication is not good for securing data. Especially sensitive information which has the potential of equating into the loss of revenue or a loss of privacy upon exposure.
When implementing an HTTP authentication scheme think of Basic Authentication as a key code allowing authorized entry into a building or office only when security staff is onsite. After business hours, the same doors are locked with a more secure mechanism to secure the building.
- access control is convenient access to authorized personnel
- security keeps property secure from attackers
Below is an illustration of a Basic Authentication request/response:
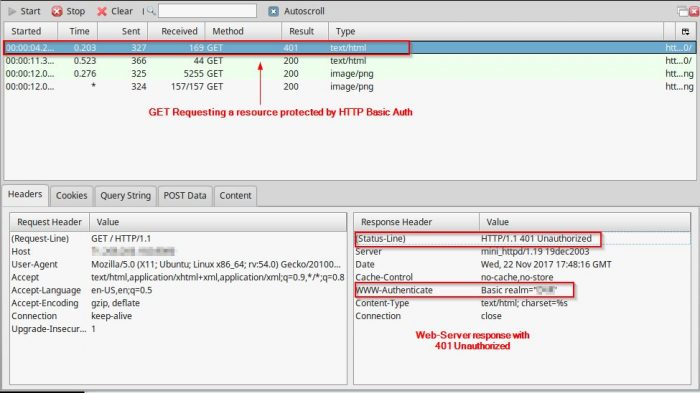
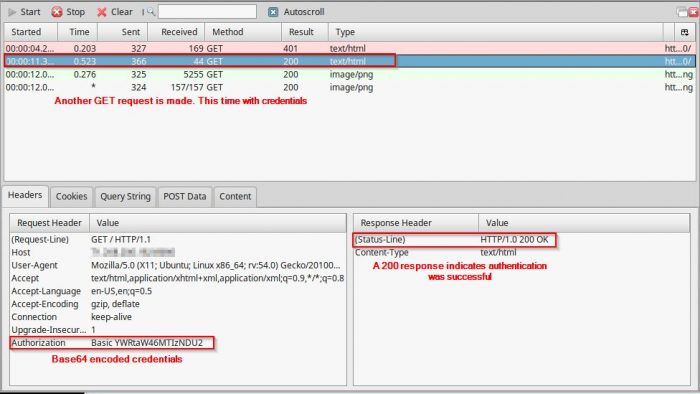
- User-Agent makes a request for a document
- Web-Server responds with HTTP Code 401: Authorization Required
- User-Agent repeats the request with credentials
- Web-Server allows or denies access based on credential validity
As a demonstration of Basic Authentication shortcomings, try figuring out credentials from the depicted BASE64 encoded string.
Bearer Token Based Authentication
Bearer Token Based authentication is popular amongst authentication framework providers. Bearer Authentication can also be deployed as a stand-alone, per instance solution.
Bearer Authentication is based on tokens and used in both OAuth and OpenID frameworks. Typically OAuth is used for authorization while OpenID is for Authentication. However, several gray areas exist blurring the lines of Authentication and Authorization in each framework.
- OpenID provides federated authentication or login services
- OAuth provides delegated authorization
GitHub provides an OAuth Guide for developers of 3rd party applications wishing to access GitHub resources on behalf of an end-user. GitHub OAuth App Guide
Large identity providers such as Google offer sign-in through OpenID Connect, the current OpenID standard, which is built on OAuth 2.0.
Login using OpenID Connect with a Google Account:
Digest Authentication
Digest Authentication is more secure than Basic Authentication. However, Digest Authentication is still inadequate at securing sensitive material on the Internet. Digest Authentication does not encrypt credentials, it hashes them, and if those hashes are captured an attacker can launch an offline brute-force or dictionary attack.
Both Digest and Basic authentication schemes are considered weak in the grand scheme of data security. Each has faults and each has been successfully attacked. When more than basic access control or authorization is needed a more secure authentication scheme must be deployed.
Other HTTP Based Authentication Schemes
NTLM known as NT Lan Manager Authentication is a Microsoft technology with plugins for many 3rd party products, operating systems, and services.
In Windows domains the preferred choice is Negotiate, which uses Kerberos and falls back to NTLM only when it has to; Microsoft is phasing NTLM out. With Kerberos, domain users who have already logged in can access authorized resources without entering their credentials again.
The biggest drawbacks to NTLM based authentication are:
- it can be cumbersome to implement on platforms other than Windows
- can lose a lot of security features if deployed outside a Windows Domain
- NTLM is only secure as the corporate network
- Older versions of NTLM are considered insecure
SCRAM-SHA1 & SCRAM-SHA256
SCRAM is an acronym for Salted Challenge Response Authentication Mechanism
When needing to authenticate internal employees SCRAM Authentication coupled with OpenLDAP may be a good solution for heterogeneous vendor environments.
SCRAM can be more sophisticated to deploy than NTLM for a Windows Domain. But SCRAM can be a great choice on a network with Linux, MacOS Server, Windows and Unix clients and even over the Internet.
From the EuroVPS blog archive, first published 12 December 2017.
All field notes