
Managed support: The people who rack it
answer your ticket.
- Our median first response to a customer ticket over the past twelve months.
- Three minutes
- The share of tickets solved within the hour, across our ticket history.
- 87 percent
- Engineers on shift around the clock, every day of the year.
- 24/7/365
Measured from our own ticket records, counting a reply from an engineer, not an automatic acknowledgement.
24/7 engineeringPeople on shift around the clock
A named engineerSomeone owns the next step
Management includedAcross every managed product
From OS to hardwareThe team behind the whole stack
When something needs attention
A conversation with
the people doing the work.
An alert can open the conversation. So can you. Either way, the engineer looking into it can work on the server, storage and network behind it.
Many tickets start with us: monitoring opens the conversation before you notice.
The everyday work
Most support is
taking care of the details.
A patched server. Working mail. A certificate renewed. The regular operational work is part of the service from the start.
Control panels
cPanel, WHM and Plesk administration. We look after the panel, investigate account problems and agree the software your setup needs.
Security & cleanup
Server hardening, malware investigation and hands-on cleanup. Outbound spam monitoring helps us find compromised accounts.
Email delivery
SPF, DKIM, mail queues and blacklist recovery. Help with the services your team and customers rely on every day.
OS & stack updates
Patching and security updates, with maintenance windows agreed around your workload. We also plan larger operating-system moves.
DNS & certificates
DNS configuration, reverse DNS and SSL installation and renewal. The work around the website is part of management too.
Monitoring & investigation
Observium, Graylog, Percona PMM and Zabbix, backed by engineers who can investigate the infrastructure behind an alert.
When the work goes deeper
The same team.
All the way down.
Infrastructure problems rarely stop at one layer. Our engineers can follow them from the application environment into the systems underneath.
A planned migration
Inventory, destination build, validation and an agreed cutover. Our engineers carry out the move and keep a rollback path in the plan.
Managed migrationsStorage down to the fabric
The team running your server also operates our HPE 3PAR arrays and dual Brocade Fibre Channel fabrics.
Our storage platformRecovery you can prepare for
Off-site backups and recovery planning around your data. Retention, restore tests and any cross-site DR scope are agreed with you.
Backups & recoveryPerformance across the stack
Investigation across the OS, database, web server and network. We give your developers findings they can act on.
Sizing for the workloadA network we operate
Our own AS200477, BGP and upstream connections. The engineers looking into a routing issue work with the network itself.
Inside our networkA managed perimeter
Dedicated firewall policy and network separation for your environment, with the changes and ongoing management handled by our team.
Managed firewallsWho answers
Engineers
at every step.
The people who answer your tickets are engineers with access to your platform, the same team that designs, builds and runs it. They can log in, read the logs and fix the problem, not just log it and pass it on.
When an issue needs a specialist, it goes straight to the engineer who knows that part of your platform, with the full context attached, so you never explain it twice.
If your service includes a contracted first-line arrangement, for example a partner who handles your own end users, it works exactly as agreed, and everything that reaches us lands with an engineer.
On the floor. On the ticket.
The infrastructure is ours.
So is the responsibility.
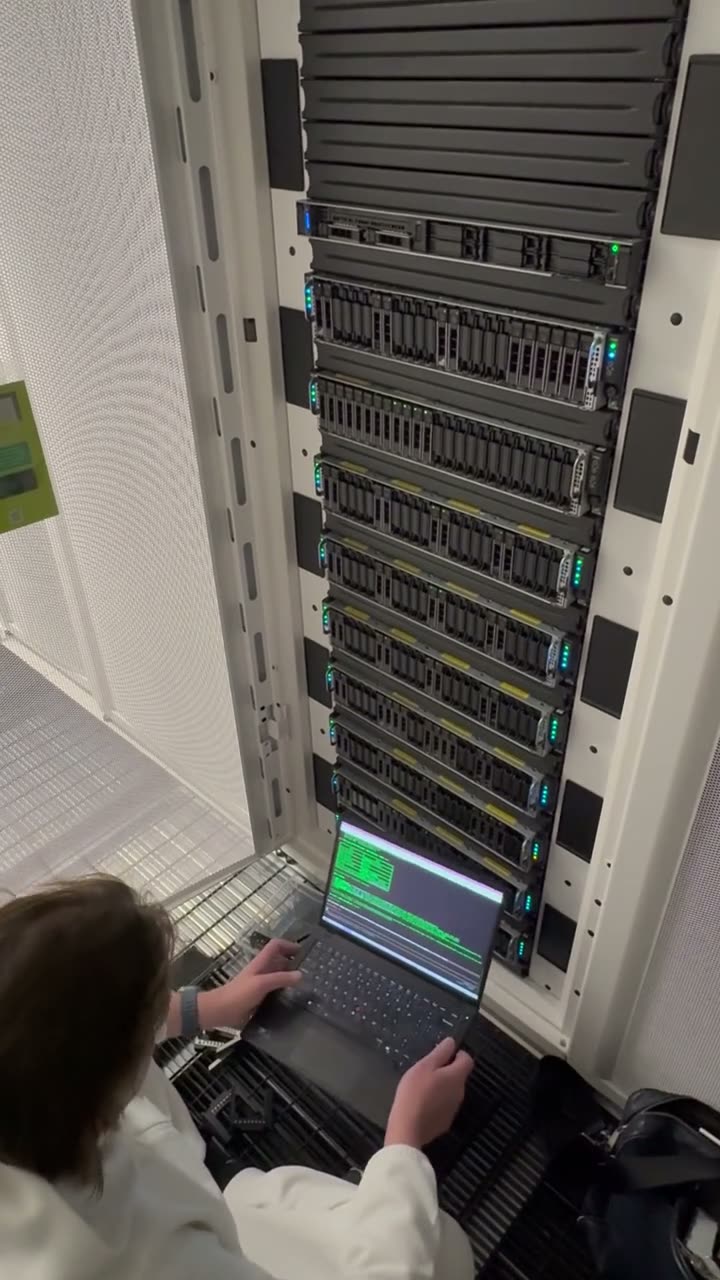
The team that answers your ticket also racks the hardware, runs the network and works at the console when a server needs attention.
Every ticket
How we work.
Minutes, not hours.
Three-minute median first response over the past year; 87 percent of tickets solved within the hour across our ticket history. Hardware tickets are typically answered in single-digit minutes.
We often open the ticket first.
Our monitoring watches your servers, your network path and your real pages. When something looks wrong, we start work and tell you, frequently before you notice.
A named person on every reply.
Every reply is signed by the engineer who wrote it.
A direct channel for larger platforms.
Customers with larger or more complex platforms can have a dedicated chat channel with our engineers alongside the ticket system.
Answers with evidence.
When you ask what happened, you get a timeline from our monitoring, logs and telemetry, not a guess.
Changes done carefully.
If a change could touch your traffic, we agree the timing with you first.
Proactive, around the clock
We call you,
not the other way round.
Our NOC watches every customer server and cluster around the clock, with the monitoring our own platform runs on: hosts, services, storage, network paths and the application ports that matter to you. When something degrades, an engineer acts first and tells you second: the fault is investigated and repaired, and you receive an outbound ticket, or a message in your private Mattermost channel if your account has one, describing what was found and what was done. Every incident also produces a written PDF report: what happened, what was repaired, what was done on our side, and anything left open on yours, for example a change your developers need to make in the application, with the action plan to close it.
The same discipline applies to vulnerabilities. When PHP2Shell was disclosed, and before it the Linux kernel flaws published as Copy Fail, Dirty Frag, GhostLock, Bad Epoll, Januscape and OVSwrap, the ssh-keysign race, the nginx rewrite module flaw, the Plesk and LiteSpeed plugin advisories, our engineers rolled the fixes out across every managed server as they were verified and checked that the hosted applications came back cleanly. Where the distribution’s packages had not yet shipped, we built and signed the patched packages ourselves and deployed them as the interim fix, then replaced them with the vendor builds when they arrived. Each customer was told what was patched, when, and how it was verified.
What it looks like
In practice.
A late-night question, answered within the hour.
On the evening a critical security flaw was patched across the internet, a customer’s developer asked whether his servers had been covered. Within the hour he had his answer: every one of them patched, with the same number of working sites before and after.
A dedicated channel that has run for years.
One of our larger customers has worked with our engineers through a dedicated chat channel for years, alongside the ticket system. Day-to-day questions, planned changes and urgent issues reach the people who run the platform directly.
A national news publisher, supported where its readers are.
The publisher moved to Digital Realty Athens, close to the readers who make up almost all of its audience, and is supported by the same engineers who built its platform there.
Real-time support on Mattermost
Talk to the engineers who run
your platform, as it happens.
Tickets are how every EuroVPS customer reaches us, and they are answered by engineers, not a script. When your team wants more than that, we give you a private Mattermost channel with our engineers in it: you write, an engineer answers, and the conversation stays on record next to your platform’s history. No phone tree, no queue, no “we will call you back”.
Included
With our enterprise-class offerings: private cloud, dedicated clusters and managed platforms come with Mattermost support for your team.
Available on any plan
As an add-on at €300 per user per month, from a single virtual machine to a dedicated server.
On our own platform
Runs on our own Mattermost, hosted in our own datacenters, with your channel visible only to your team and our engineers.
The practical details
What to expect
from your team.
Talk through responsibilities, escalation and the scope of your setup with the engineers who will look after it.
Ask an engineerOver the past twelve months our median first response was three minutes, and across our ticket history 87 percent of tickets were solved within the hour. These are measured from our own ticket records and count a reply from an engineer, not an automatic acknowledgement. Contractual response commitments are part of your service agreement; ask us for the terms that fit your platform.
Your next infrastructure partner
Talk to the person
who will actually fix it.
Tell us what you run and where your team needs support. We’ll work through the infrastructure, management scope and next step with you.
Existing customers: open a ticket in the client area, 24/7Talk to an engineer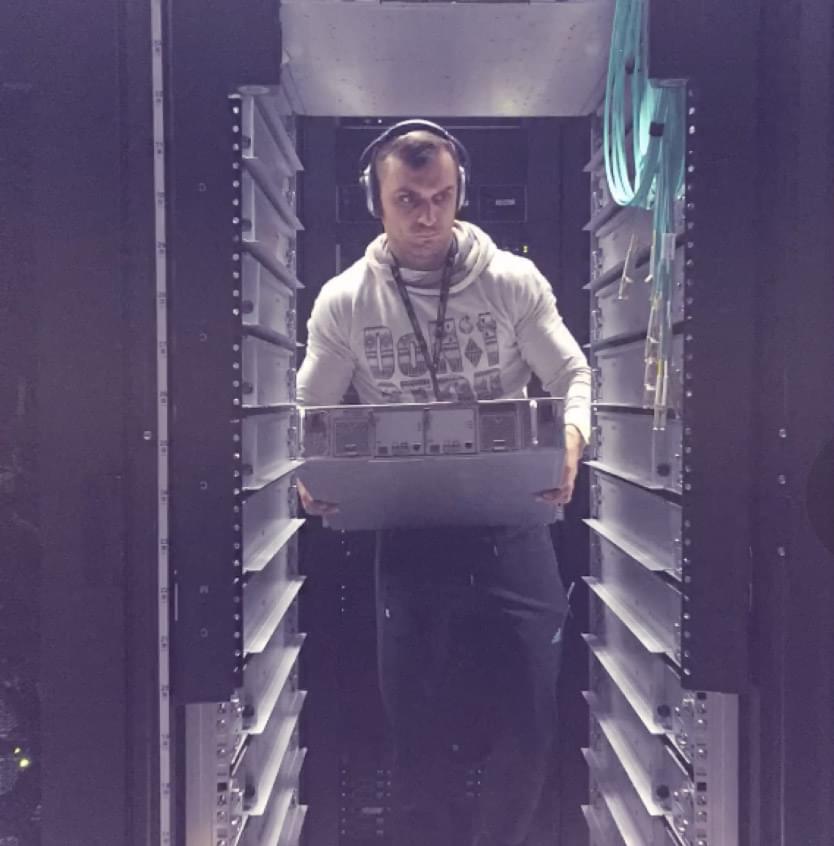
who will look after your infrastructure.
Let’s start with your setup.
A little context helps us start the right conversation.
From the engineering team